vLLM¶
The latest version tag checked on 2026-09-30 is v0.31.0rc2, a release candidate. This page considers full-attention request scheduling and KV cache in that tag. The existing executable program is a restricted synchronous model; its historical oracle results do not establish equivalence with the entire latest scheduler.
Tagged behavior¶
Scheduler.schedule shares a token budget between resident and waiting requests, using computed progress to determine selected work. Allocation failure triggers victim selection: FCFS and priority paths choose differently. Scheduler
KVCacheManager.get_computed_blocks finds reusable prefixes, while allocate_slots acquires space for scheduled work and lookahead. Identical prefixes can share blocks across requests, requiring more than a session's cached length. KV manager
The scheduler guards whether victim blocks can actually be freed and manages deferred free. AsyncScheduler tracks output placeholders and in-flight results. Releasing or publishing KV before completion can create invalid reuse. Victim/free guard, async scheduler
Executable serQ model¶
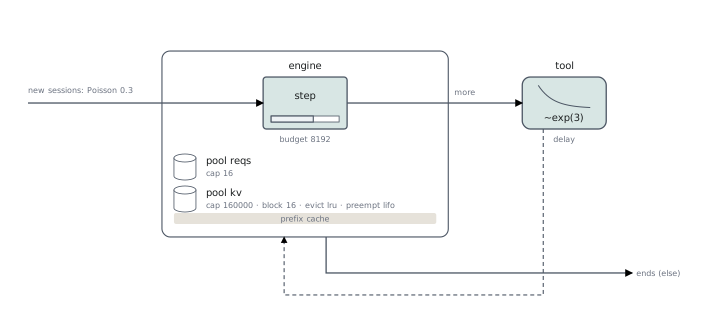
// vLLM v1 on one device (ref/vllm at 0c87a197, `vllm/v1/core/sched/
// scheduler.py`, `kv_cache_manager.py`, `block_pool.py`), as a serQ
// program. Continuous batching with chunked prefill: every iteration hands
// a token budget to the running requests in admission order (one token per
// decoding request, up to `chunk` per prefilling one), then admits waiting
// requests FCFS while the request cap and the KV blocks allow, the first
// that does not fit blocking the rest. KV memory is a block pool with a
// block-level LRU prefix cache: a finished (or preempted) request's full
// blocks stay cached and are evicted tail first when the free queue is
// drained; the next turn of a session reuses its cached prefix (full blocks,
// never the whole prompt). A request grows one block at a time as it
// decodes; when no block is free the most recently admitted request is
// preempted (its blocks freed to the cache, it re-enters the waiting queue
// at the head and recomputes what was lost). See docs/language.md
// §"vLLM" for the line-by-line correspondence.
use "../../lib/vllm.sq";

let B = 8192;          // max_num_batched_tokens
let max_seqs = 16;     // max_num_seqs
let blocks = 10000;    // num_gpu_blocks (less the null block)
let bs = 16;           // block_size
let chunk_cap = 0;     // long_prefill_token_threshold (0: none)
let a = 2e-5;          // compute per scheduled token (s)
let omega = 2e-4;      // weights read per iteration (s)
let beta = 2e-9;       // KV read per iteration per resident context token (s)
let c0 = 0;            // fixed cost per iteration (s)
let Lambda = 0.3;      // sessions per second
let p = 0.9;           // continue after a turn
let Z = 3.0;           // tool time (s)

pool kv { cap blocks * bs; block bs; evict lru; preempt lifo; }
pool reqs { cap max_seqs; }

stage engine : step {
  budget B;
  chunk chunk_cap;
  cost c0 + max(omega + beta * (kv_decode + kv_prefill), tokens * a);
  memory kv;
}
stage tool : delay;

// The client: sessions arrive, each turn brings a prompt of n new tokens
// on a context of K and wants o tokens back, and after a turn the session
// calls a tool and comes back with probability p. Nothing here is vLLM.
workload {
  arrive poisson(Lambda);
  hidden o;              // the scheduler knows max_tokens, not the length (sched/utils.py:98-119)
  init { set K = 0; }
  turn {
    set n = K == 0 ? ~uniform(1000, 3000) : ~exp(500);
    set o = ~exp(200) + 1;
    set more = ~bernoulli(p);
  }
  session {
    turn;
    loop {
      request;
      set K = prompt + o;
      branch (more) { tool (~exp(Z)); turn; } else { end; }
    }
  }
}

// The engine: what vLLM does with one request.
server {
  set t0 = now;
  set prompt = K + n;
  vllm_request(reqs, kv, engine, prompt, o, t0);
  observe response = now - t0;
}

run { horizon 2000; warmup 200; seed 1; }
The program shares its request definition with the other existing workloads:
// vLLM v1 (ref/vllm at 0c87a197, `vllm/v1/core/sched/scheduler.py`,
// `kv_cache_manager.py`, `block_pool.py`) as definitions a program uses:
// `use "…/lib/vllm.sq";`. docs/language.md §7 has the line-by-line
// correspondence.

// What a cache hit may cover of a request of x tokens: its full blocks of
// `bs` tokens, and never the last token, which is computed for its logits
// (kv_cache_manager.py:289-300).
def reusable(x, bs) = floor((x - 1) / bs) * bs;

// One request of `prompt` tokens that wants `o` back, sent at `t0`, through
// vLLM's scheduler and one engine: a slot of `reqs` and the blocks of `kv`,
// continuous batching with chunked prefill on `engine`.
//
// The prefix hit (full blocks, never the whole prompt) is looked up when
// the scheduler admits (scheduler.py:932-939), and the admission takes the
// hit plus the chunk the budget allows (scheduler.py:1078-1128, 1214-1226);
// docs/language.md §7 "Admission" has the argument. `known` is every token
// the request has: the prompt, or after a preemption the position it had
// reached plus the token sampled there (vLLM keeps the generated tokens and
// drops only their KV, scheduler.py:1560-1561); the hit can cover all but
// the last of them.
//
// A definition's names are the program's: the request binds `known` in its
// admission, sets the attribute `c`, and observes at each admission (again
// after a preemption) `hit` (c > 0: any reused block counts, a turn that
// lost only its tail blocks too) and `prefill_tokens` (known - c; on a first
// admission known = prompt, and the share the cache supplied, c / prompt,
// is not observed), and `ttft` (time to first token, from `t0`).
def vllm_request(reqs, kv, engine, prompt, o, t0) {
  hold reqs (1), kv (min(known, hit + budget_left(engine)))
       at admission (known = computed < prompt ? prompt : computed + 1,
                     hit = min(cachedin(kv), reusable(known, blocksize(kv)))) {
    set c = min(cached, reusable(known, blocksize(kv)));
    observe hit = c > 0;
    observe prefill_tokens = known - c;
    prefill on engine (known - c) growing kv;
    branch (known == prompt) { observe ttft = now - t0; }   // not a resumed request's re-prefill
    decode on engine (o - 1 - (known - prompt)) growing kv;
  } cache (prompt + o);
}
| Requirement | Current expression | Limit of the model |
|---|---|---|
| Token budget and chunked prefill | step { budget …; chunk …; } |
Resident selection then waiting admission is a specific policy |
| Request slots and KV space | hold, admission bindings, reserve, growing |
Match all tagged fit/lookahead conditions with an oracle |
| FCFS/priority | Queue order and preempt lifo |
Priority victim selection is not the LIFO mechanism |
| Shared prefix | cachedin, reuse, cache |
Cache identity is session-based, not content-key shared objects |
| Local decode preemption | computed-aware known in vllm_request |
Latest-tag recovery paths need differential validation |
| Async and speculative execution | Cost expressions, explicit leases/transfers | In-flight scheduler state and proposed/accepted progress remain absent |
Validation and next scenarios¶
How serQ is checked records the existing scheduler scenarios and trace. Those checks apply to their stated reference and paths, not to every feature of v0.31.0rc2. Current local recovery already accounts for known generated progress; the older IR v4 discussion is a historical design record, not a list of current missing features.
For the latest tag, compare priority victims, output-preserving decode preemption, cross-request prefix sharing and deferred free of in-flight blocks. Observe per-step selection, physical allocation/reuse, committed tokens and release times.
See vendor plugins for each repository's latest tag, executable model and remaining limitations.